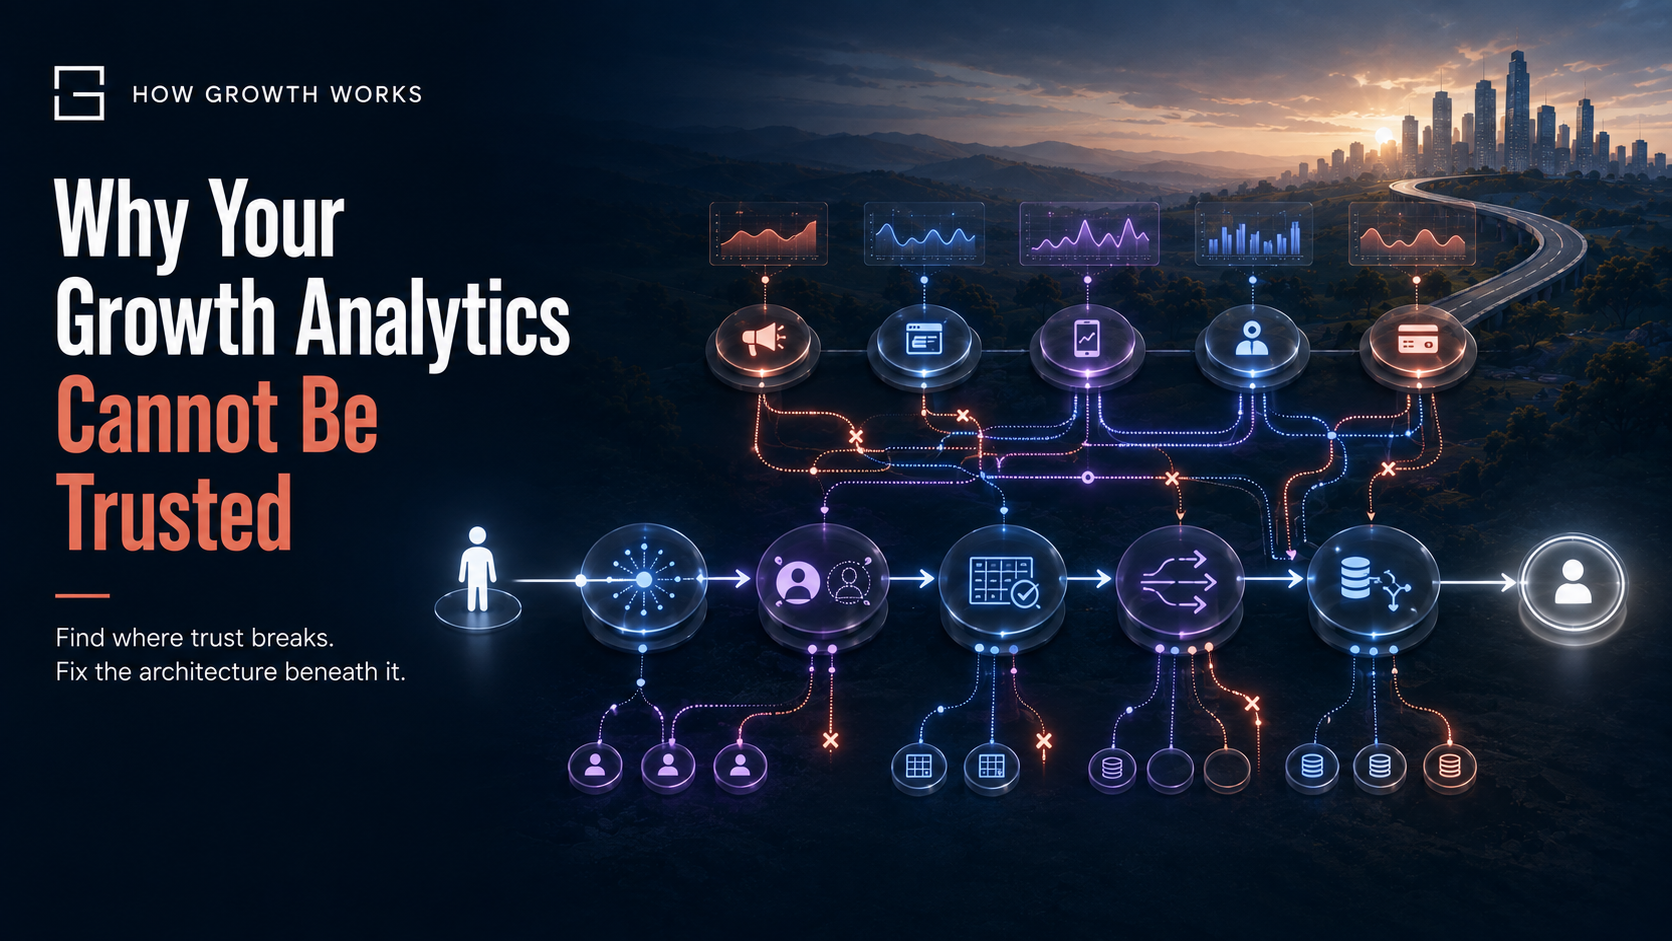
The paid media dashboard says 1,284 conversions.
Google Analytics reports 913.
The CRM contains 846 new customers.
The payment processor shows 821 successful first payments.
Finance recognises revenue from 798.
Five systems. Five answers.
The usual response is to ask which number is correct.
That is often the wrong first question.
Each system may be counting a different event, over a different time window, for a different entity and under a different attribution rule.
One may include view-through conversions. Another may count only observed website sessions. The CRM may include manually created customers. The payment platform may exclude failed charges. Finance may account for refunds, taxes, deferred revenue and recognition timing.
Some discrepancies are evidence of broken tracking. Others are legitimate consequences of asking different questions.
The real task is to know which is which.
Most growth analytics problems are not dashboard problems. They are architecture problems. They begin with events that were never specified, customer identities that were never reconciled, metrics that were never precisely defined and systems whose authority was never established.
By the time the problem appears in a dashboard, the dashboard can only visualise the ambiguity it inherited. This is one of the clearest signs that your business has outgrown its tech stack: the tools still operate, but the business no longer shares a dependable version of what happened.
The goal is not perfect data. Perfect observation is unavailable in most digital businesses. The goal is an analytics system that is reliable enough for the decision being made and explicit about what it cannot know.
Why can growth analytics not be fully trusted?
Growth analytics becomes untrustworthy when the business cannot explain how a number was collected, which customer or account it belongs to, how the metric was defined, which attribution rules were applied and which system is authoritative.
The five layers of analytics trust are:
- Instrumentation: Are the right events being recorded correctly?
- Identity: Are those events attached to the right person or account?
- Definitions: Does everyone mean the same thing by the metric?
- Attribution: What can the data show about the route to conversion, and what can it not prove about causation?
- Reconciliation: Do systems agree where they should, and can legitimate differences be explained?
Key takeaways
- GA4, ad platforms, CRM and finance can disagree because they measure different things.
- An SDK does not guarantee reliable instrumentation, and fragmented identity corrupts funnels and cohorts.
- An undefined metric is unsafe for consequential decisions.
- Attribution assigns credit to observed interactions; it does not prove what caused a conversion.
- Better dashboards and AI analysis cannot repair unreliable source data.
- The correct objective is Decision-Grade Data, not imaginary perfection.
What makes growth analytics trustworthy?
Trustworthy analytics is not one number reproduced by every system. It is a controlled relationship between a number and a decision.
Directional platform data may be enough to pause an advertising creative. Payment-failure messaging needs customer-level billing events. Recognised revenue needs finance-grade definitions.
This is Decision-Grade Data: data whose quality, definition, timeliness and limitations are sufficient for a specified decision.
To determine whether data is decision-grade, ask:
- What exactly does this number mean?
- Which entities does it include, and which system produced it?
- What can prevent that system from observing the underlying event?
- Is it fresh enough, and what discrepancy is acceptable?
- What should we not infer from it?
Trust is not binary.
A metric can be useful for weekly trend detection and unsafe for calculating sales commission. It can be good enough for product exploration and inadequate for reallocating half the marketing budget.
The right question is not simply, “Is this data accurate?”
It is, “Is this data sufficiently reliable for this decision?”
How the Analytics Trust Hierarchy works
Analytics trust is built from upstream foundations:
Collection → Identity → Definition → Reconciliation → Decision
Collection asks whether the right event was recorded correctly.
Identity asks which person, user or account it belongs to.
Definition determines how those observations become a metric.
Reconciliation compares the metric with other systems where comparison is meaningful.
Decision establishes whether the result is adequate for the action being considered.
Visualisation sits after these layers. Attribution is a specialised measurement problem that depends on all of them.
If collection is unreliable, a sophisticated attribution model only processes incomplete inputs.
If identity is broken, funnels and cohorts describe fragments rather than customers.
If definitions conflict, dashboards cannot create organisational agreement.
If systems are not reconciled, decision-makers cannot distinguish expected variation from failure.
Better visualisation cannot compensate for weak analytics architecture.
Layer 1: Analytics instrumentation
Analytics instrumentation is the design and implementation of the events used to observe behaviour. It determines what is recorded, when an event fires, which properties accompany it and how the event is validated.
Installing an analytics SDK does not complete this work.
An SDK can transmit an event called signup_completed, but it cannot decide:
- whether the event fires on form submission, account creation or email verification;
- which IDs and properties it must contain;
- how to prevent duplicates and keep web, mobile, client and server implementations consistent.
A tracking plan should define every decision-critical event, its trigger, required properties, source, owner and validation rules.
Amplitude describes a tracking plan as defining every event and property, why it is collected and which source emits it. Segment and Snowplow provide schema validation because technically valid transport is not the same as semantically valid data.
Common analytics instrumentation failures include:
- an event firing twice because both the application and tag manager send it;
- a purchase firing when the confirmation page loads, so a refresh creates another purchase;
- an activation event disappearing after a product release changes a button or route;
- properties arriving with inconsistent values or data types;
- server-side and client-side versions of the same event being counted together;
- test, staff and bot activity entering production reports.
These failures rarely announce themselves.
The dashboard still loads. The chart still has a line. The number still appears precise.
Client-side versus server-side tracking
Client-side tracking is useful for page views, clicks and interface behaviour, but it can be interrupted by:
- consent choices;
- browser restrictions;
- ad blockers;
- navigation;
- network failure.
Safari, for example, blocks third-party cookies by default and imposes additional restrictions intended to reduce cross-site tracking.
Server-side tracking is usually more dependable for events the server knows occurred, such as account creation, order completion, subscription renewal or cancellation. It can also capture offline interactions.
But server-side tracking is not an accuracy switch.
It still requires correct identity, idempotency, consent handling and event mapping. If a client and server both send the same purchase without a clear deduplication rule, a supposedly more robust implementation can produce less reliable data.
Google explicitly describes GA4’s Measurement Protocol as a supplement to automatic collection, not a universal replacement.
The correct principle is simple: use the most authoritative observation point for each event, then make the relationship between client-side and server-side events explicit.
Why can Google Analytics data appear inaccurate?
Google Analytics data can appear inaccurate because GA4 is an event-based measurement system, not a transaction ledger.
Its reports depend on:
- the events it receives;
- consent choices;
- browser restrictions;
- identity settings;
- attribution settings;
- filters;
- modelling.
If a purchase event is missing, duplicated or blocked, GA4 can differ from the payment processor even when the payment record is correct.
If GA4 uses a blended reporting identity, some reports may also include modelled behaviour.
This does not make GA4 useless. It means GA4 should be authoritative for defined analytics use cases, not treated as financial truth.
Instrumentation must also be maintained as products and checkout flows change.
For consequential events, quality assurance should include pre-release testing, production monitoring, volume checks, duplicate detection, property validation and periodic end-to-end journeys.
Ownership should be named. “The data team” is not an owner.
Layer 2: Customer identity resolution
An event can be perfectly recorded and still be attached to the wrong customer.
Before login, a browser or application normally assigns an anonymous identifier. After signup or login, the business has a known user ID.
If those identities are not joined correctly, the analytics platform sees two people:
- the anonymous visitor who explored the product;
- the known user who converted.
That break distorts the funnel. The top appears larger, the conversion rate appears lower and acquisition activity can become detached from revenue.
Customer identity resolution becomes harder when:
- one person uses several devices or browsers;
- cookies expire or are blocked;
- one person uses several email addresses;
- several users share a device;
- a B2B account contains many individual users;
- CRM, product and billing systems assign different IDs;
- records are incorrectly merged or duplicated.
Mixpanel and PostHog both document explicit anonymous-to-known identity flows because no analytics platform can safely infer your customer model from events alone.
GA4 offers different reporting identities using combinations of User-ID, device ID and modelling. Changing identity rules can therefore change the reported number of users without any change in actual demand.
What entity are you analysing?
The first architectural decision is the unit being analysed:
- person;
- product user;
- household;
- workspace;
- company account;
- subscription;
- contract.
In B2B SaaS, counting users when the commercial entity is an account can make expansion, churn and lifetime value incoherent.
Use durable internal IDs as the backbone of customer identity.
Email is a useful attribute, but it is mutable and may not be unique. Preserve the mappings between:
- anonymous ID;
- product user ID;
- account ID;
- CRM contact ID;
- CRM account ID;
- billing customer ID;
- subscription ID.
Define merge and split rules. Test logout behaviour, shared devices, guest checkout, multiple accounts and returning users on new devices.
This connects directly to What Should Be the Source of Truth for Customer Data?. Identity resolution is not about copying every identifier into every tool. It is about establishing authoritative identifiers and controlled mappings between systems.
Layer 3: Metric definitions
The most damaging analytics disputes often happen when everyone uses the same word.
Consider “customer.”
It might mean:
- anyone who created an account;
- anyone who placed an order;
- anyone whose first payment succeeded;
- anyone with an active subscription;
- any company with a signed contract;
- any account with recognised revenue in the period.
Each definition can be valid.
They are not interchangeable.
The same problem applies to lead, activation, churn, revenue and conversion rate.
Purchase events divided by sessions is not the same metric as new paying customers divided by unique identified visitors.
Two dashboards can therefore be technically correct and organisationally contradictory.
Create a Metric Contract
Every decision-critical metric should have a Metric Contract.
| Field | What it establishes |
|---|---|
| Name | The canonical label |
| Business question | The decision the metric supports |
| Precise definition | What the metric means |
| Numerator | What is counted above the line |
| Denominator | The eligible population or base |
| Inclusion and exclusion rules | Tests, refunds, staff, duplicates, plans and other boundaries |
| Entity and grain | User, account, subscription, order or transaction |
| Source | Where the inputs originate |
| Authority | Which system settles disputes about the underlying fact |
| Calculation | Formula and transformation logic |
| Time basis | Event time, processing time, billing period or recognition period |
| Update frequency | Real time, hourly, daily or monthly |
| Owner | Person accountable for meaning and quality |
| Version | When the definition took effect |
A Metric Contract can begin as a governed table. It does not require a warehouse or semantic layer.
As the organisation grows, definitions may move into a modelling or semantic layer so BI tools, operational systems and AI agents query the same logic.
Historical definitions must be versioned
Historical versioning matters.
If “activated” changes from creating a project to inviting a teammate and publishing it, store the effective date and annotate the break in reporting.
Otherwise, the business may appear to have improved or deteriorated because the measurement changed, not because customer behaviour changed.
This is also why lifecycle design precedes lifecycle reporting.
How to Design Customer Lifecycle States explains that a state needs entry rules, exit rules and authority. If the CRM, product database and lifecycle platform each define “active” differently, an active-customer dashboard merely displays the underlying conflict.
Layer 4: Marketing attribution accuracy
Marketing attribution asks how conversion credit should be assigned among observed interactions.
Attribution accuracy therefore depends on what was observed, which interactions were eligible for credit and which attribution model was applied.
Google Ads, Meta, GA4, a CRM and a product analytics platform can all report different conversion numbers without any of them being broken.
They may differ because of:
- click-through, engaged-view and view-through eligibility;
- different attribution windows;
- first-touch, last-touch or data-driven allocation;
- conversion date versus ad-interaction date;
- cross-device identity;
- consent, tracking loss and dark social;
- different conversion definitions, counting rules and late-arriving events.
Advertising platforms also have an incentive to demonstrate their contribution.
That does not make their data useless. It means platform-attributed performance should be interpreted as one measurement view, not as neutral transaction truth.
Google documents separate click-through, engaged-view and view-through conversion windows. Meta allows advertisers to choose whether credit can follow impressions, clicks or engagements.
When those settings differ, the reported results should differ.
Measurement is not causal inference
The critical distinction is between measurement and causal inference.
Measurement tells you that a conversion occurred after an observable interaction and assigns credit under a rule.
Causal inference asks whether the conversion occurred because of the marketing exposure.
What would have happened to the same customer, at the same time, if they had not seen the campaign?
No click path contains that counterfactual.
Randomised holdouts and well-designed incrementality experiments can estimate causal lift more credibly, although they still face sample-size, contamination and implementation constraints.
Research comparing observational ad measurement with randomised experiments found that observational approaches often failed to recover experimental effects even with rich user-level data.
Separate research by Lewis and Rao shows why even advertising experiments can require very large samples to measure returns precisely.
Self-reported attribution can add context for podcasts, communities, word of mouth and dark social, but it has recall limitations.
Multi-touch models describe more of the observed journey. They do not automatically identify causality.
Use attribution for the questions it can answer. Use experiments, where feasible, to estimate incremental effect.
Do not buy attribution software expecting certainty that the underlying evidence cannot provide.
Layer 5: Analytics reconciliation
Analytics reconciliation is the process of comparing systems, explaining differences and deciding which source is authoritative for each fact.
Not every number should match.
Why do GA4 and CRM data show different numbers?
GA4 and CRM data often differ because GA4 measures observed or modelled behaviour while the CRM records known contacts, accounts and commercial states.
Anonymous visitors may never become CRM records. CRM records may be created manually or imported without a tracked website session.
The systems should reconcile only where they represent the same defined event or entity.
| Metric or claim | Typical authority | What another system may legitimately report |
|---|---|---|
| Successful transaction | Payment processor or commerce backend | Purchase events observed by analytics |
| Subscription status | Billing or subscription system | Synced lifecycle eligibility in CRM or messaging |
| Commercial relationship stage | CRM | Product behaviour or billing status |
| Product behaviour | Product analytics using validated events | CRM summary fields |
| Platform-attributed conversions | Relevant advertising platform | Cross-channel attribution using another model |
| Recognised financial revenue | Finance or accounting system | Gross sales, bookings, cash collected or event revenue |
Authority depends on the architecture.
Three payment processors may require a consolidated transaction source, while a poorly maintained CRM may be the designated authority without being operationally trustworthy.
A designated source of truth can still contain bad data.
Build a Reconciliation Map
A Reconciliation Map should record:
- the metric or underlying fact;
- the systems being compared;
- the authoritative system;
- the expected reason for difference;
- the acceptable tolerance;
- the comparison frequency;
- the owner;
- the escalation rule.
Payment success and backend order completion might be expected to reconcile within a small tolerance after processing delays.
Ad-platform conversions and transactions should not match exactly. Instead, monitor the relationship and investigate structural breaks.
A sudden fall in the percentage of paid transactions observed by analytics could reveal:
- a broken purchase event;
- consent changes;
- browser restrictions;
- missing identifiers;
- an integration failure;
- a change in checkout flow.
The systems do not need to agree absolutely. Their relationship needs to be understood.
This extends the architecture described in How Customer Data Should Move Through Your Growth Stack. Data movement needs observable controls: delivery failures, freshness checks, record counts, null rates and reconciliation against the source.
Why more analytics dashboards usually do not fix the problem
When leaders cannot trust the numbers, organisations often commission another dashboard.
The new dashboard may look cleaner. It may also contain the same unresolved events, identities and definitions.
Soon Growth has one dashboard, Product has another, Finance exports a spreadsheet and the CEO asks which one is correct.
Common failure patterns include:
- adding vanity metrics because they are easy to visualise;
- allowing each team to define activation or revenue locally;
- migrating analytics tools without repairing the tracking plan;
- building a warehouse before fixing source events;
- buying attribution software to solve causal uncertainty;
- using AI to narrate unreliable data more persuasively.
A warehouse can preserve broken data at impressive scale.
BI software can standardise the display of a disputed definition.
AI can identify patterns in duplicate events.
None of those outcomes creates trust by itself.
AI does not make unreliable analytics trustworthy. It makes unreliable analytics easier to interrogate, and potentially easier to misinterpret.
Before adding another reporting layer, run a growth tech stack audit that traces the important metrics through their events, definitions, integrations and systems of authority.
The objective is not to identify which dashboard looks best. It is to locate the earliest layer at which trust breaks.
What does a minimum viable growth analytics stack look like?
A growing business usually needs this minimum analytics architecture:
- Acquisition platforms with consistent campaign parameters and clearly defined platform conversions.
- Website or product with a governed event layer and stable internal IDs.
- Analytics platform for behavioural analysis, funnels, cohorts and acquisition reporting.
- CRM and lifecycle platform receiving the customer facts and states needed for commercial work and communication.
- Payment or subscription system authoritative for transactions, invoices and subscription status.
- Finance or accounting system authoritative for recognised financial reporting.
- A lightweight reconciliation process covering the metrics used for consequential decisions.
Direct integrations are enough while the data model is simple and important facts do not require repeated cross-system transformation.
Even then, the flow needs to be designed deliberately.
Marketing Automation Architecture: What Should Actually Be Automated? explains why an automation trigger needs an authoritative event, eligibility logic, suppression rules and failure handling.
Analytics trust and automation safety are the same upstream problem viewed from different downstream uses.
When do you need a warehouse, CDP or more sophisticated data infrastructure?
Add infrastructure only in response to a demonstrated limitation.
Server-side tracking
Server-side tracking becomes useful when decision-critical events are known reliably by the backend, when offline interactions matter or when client-only delivery is too fragile.
It does not eliminate consent requirements, identity design or the need to prevent duplicates.
Customer data platform
A CDP becomes useful when governed events and identities must reach many tools consistently.
A CDP should not be introduced merely because customer data is inconsistent. Without clear identity and ownership rules, it may distribute the inconsistency more efficiently.
Data warehouse
A warehouse becomes useful when analysis requires reproducible historical joins across product, CRM, billing, support and finance.
A warehouse does not improve source data simply by storing it.
Transformation and modelling layer
A modelling layer converts raw data into tested business entities and metrics.
This is where definitions can become executable rather than merely documented.
Reverse ETL and business intelligence
Reverse ETL and BI become useful when governed warehouse outputs must return to operational tools and multiple teams need controlled access to shared models.
Start with decisions and definitions. Repair collection and identity. Then add infrastructure that removes a real bottleneck.
Complexity before governance multiplies the places where the business can be wrong.
How does AI affect analytics data quality?
Natural-language querying makes analytics accessible. Anomaly detection can surface broken events. Agents can investigate funnels, generate hypotheses and eventually act.
This increases both upside and risk.
An AI analyst with access to bad data can produce extremely convincing bad analysis.
Ambiguous event names, duplicate purchases and conflicting activation definitions do not become harmless because the answer is written clearly.
Amplitude’s guidance for preparing data for AI says that clear taxonomy and deduplicated, documented events are prerequisites for accurate answers.
Before an AI system can recommend or execute Growth decisions, it needs:
- access to governed datasets and canonical metrics;
- metric definitions and business context in machine-readable form;
- source lineage and freshness attached to outputs;
- data-quality tests and anomaly alerts;
- confidence and limitation statements;
- restricted permissions, approval thresholds, audit logs and safe rollback.
Separate read, recommend and act permissions.
An agent may be allowed to describe a drop in activation before it is allowed to change onboarding messages or reallocate advertising spend.
Autonomy should expand only after the data and control system have earned it.
The Analytics Trust Audit
Do not begin by documenting every event or dashboard.
Begin with the decisions the business actually makes.
Ask:
- What are the ten metrics we use to make consequential decisions?
- What decision does each metric support?
- How is each metric precisely defined?
- What are its numerator, denominator, entity, grain and time basis?
- Which system calculates it?
- Which system is authoritative for the underlying fact?
- What events and properties does the calculation depend on?
- Who owns those events, and when were they last tested end to end?
- How are anonymous and known users reconciled?
- How are individual users mapped to accounts, subscriptions or contracts?
- Where can tracking, delivery or transformation fail?
- Which systems should reconcile, and why?
- What discrepancy is acceptable after timing and scope differences are considered?
- Which differences are expected because the systems answer different questions?
- Have definitions changed historically, and are those changes versioned?
- Does the dashboard distinguish observed, modelled and attributed data?
- What decisions should we not make from this data?
- What alert tells us the metric has become unreliable, and who owns the response?
The outputs should be small and operational: ten decision-critical metrics, their Metric Contracts, a tracking plan, an identity map, a Reconciliation Map and a repair backlog ranked by decision risk.
Prioritise a broken payment event used for revenue decisions over a missing low-value engagement property.
The purpose of the audit is not analytic tidiness. It is to reduce the chance of making an expensive decision from misunderstood evidence.
How to build trustworthy growth analytics
Start with one consequential decision, not a stack-wide transformation.
Choose the metric supporting that decision.
Write its Metric Contract.
Trace every input back to its source.
Test the dependent events.
Inspect identity transitions.
Compare the output with the authoritative operational system.
Explain the remaining difference.
Decide an acceptable tolerance.
Assign an owner.
Then repeat.
This creates trust through evidence rather than assertion. It also reveals whether the next investment should be instrumentation repair, CRM discipline, identity resolution, a modelling layer or simply clearer language.
The organisation does not need every dashboard to show the same number.
It needs every important number to declare what it is, where it came from and what it is safe to conclude.
Your growth analytics will never observe everything.
They do not need to.
They need to be reliable enough for the decision, honest about uncertainty and governed strongly enough that a precise-looking dashboard cannot quietly redefine reality.
Frequently asked questions about growth analytics
Why do analytics platforms show different numbers?
They may use different event definitions, identities, attribution windows, time zones and counting rules. Investigate when systems intended to measure the same fact differ beyond an accepted tolerance.
Which system should be the source of truth for analytics?
There is rarely one universal source of truth. Assign authority fact by fact: payments for transactions, CRM for commercial state, product analytics for validated behaviour and finance for recognised reporting.
Is GA4 accurate enough for growth decisions?
Yes, for defined acquisition and behavioural questions when its instrumentation is tested and limitations understood. It should not replace payments or finance for transaction and revenue truth.
Can marketing attribution determine what caused a sale?
No. Attribution assigns credit under a rule; incrementality experiments and other causal methods estimate what might have happened without the marketing exposure.
Does server-side tracking solve analytics data quality?
It can make backend-confirmed event collection more durable, but it does not solve ambiguous definitions, incorrect identity mapping, duplicates, consent requirements or faulty business logic.
What should a business fix first?
Start with the most consequential metric. Define it, trace its events, test identity, establish authority and reconcile the result before buying another tool.
Leave a Reply